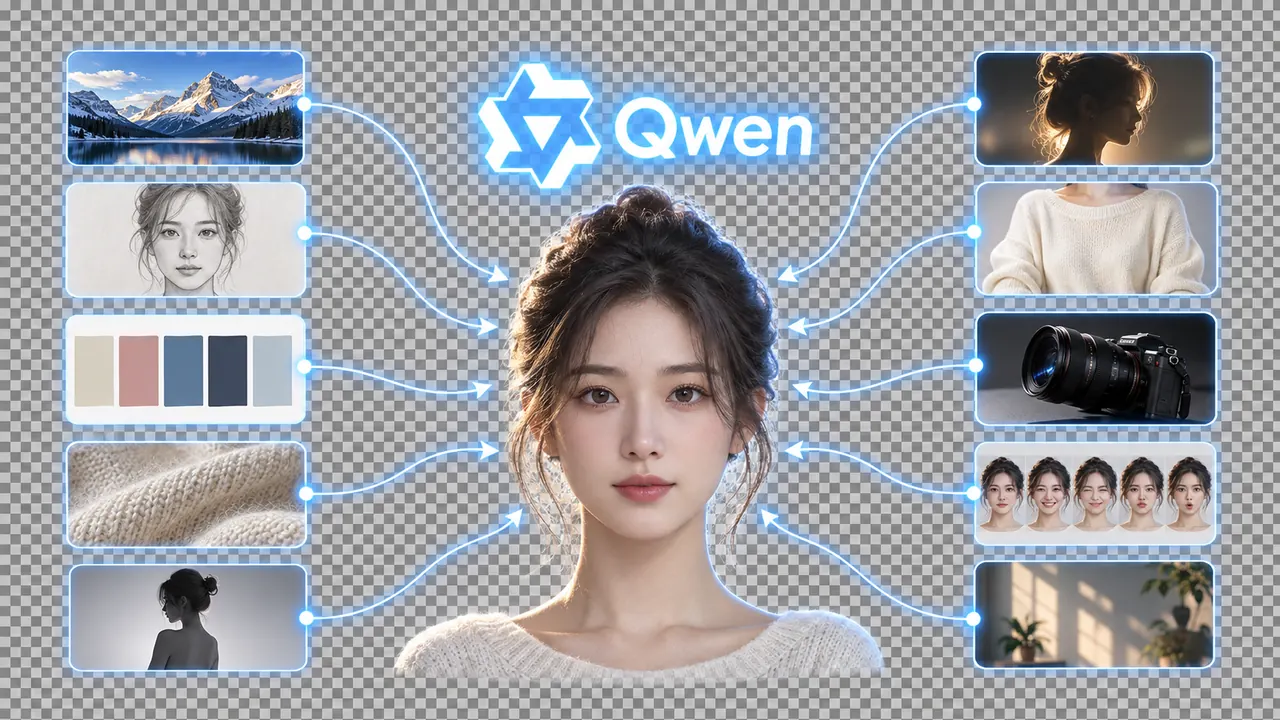
Alibaba's Qwen team pushed weights to Hugging Face at 09:41 UTC Saturday, September 20: a 7B single-stream diffusion transformer with a Qwen3-VL 8B text encoder and a 64-channel RGBA autoencoder, so transparency is generated natively instead of matted in post. It takes up to 10 reference images, does mask/circle/annotation-driven local editing, and outputs native 2K. The catch for working creators: it's the Qwen Research License — free for research and eval, and commercial deployment needs a separate paid license from Hangzhou Tongyi Laboratory.
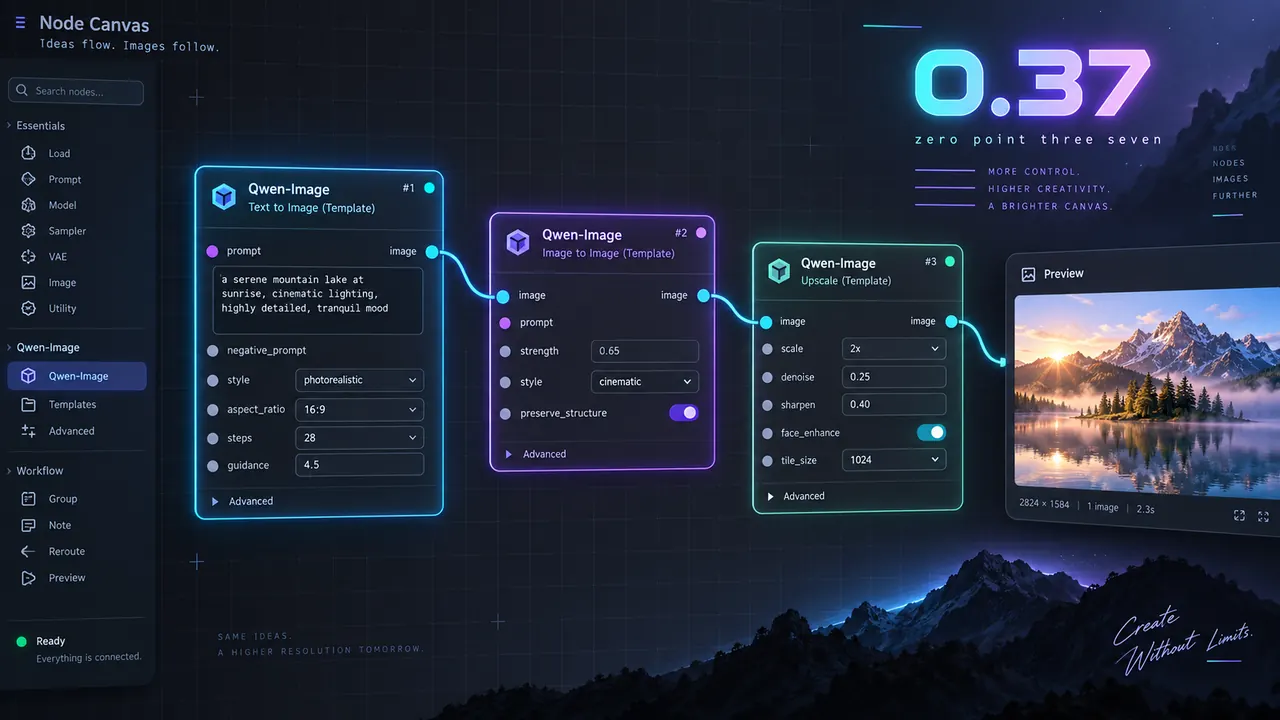
Comfy-Org cut v0.37.0 on September 20 with three official Qwen-Image 2.1 templates plus MoGe 3 geometry estimation, landed by Kijai in PR #16381. Same-day native support means no custom node archaeology — you update, load a template, and you're generating RGBA layers. That's a genuinely fast turnaround from weight drop to production-ready graph.
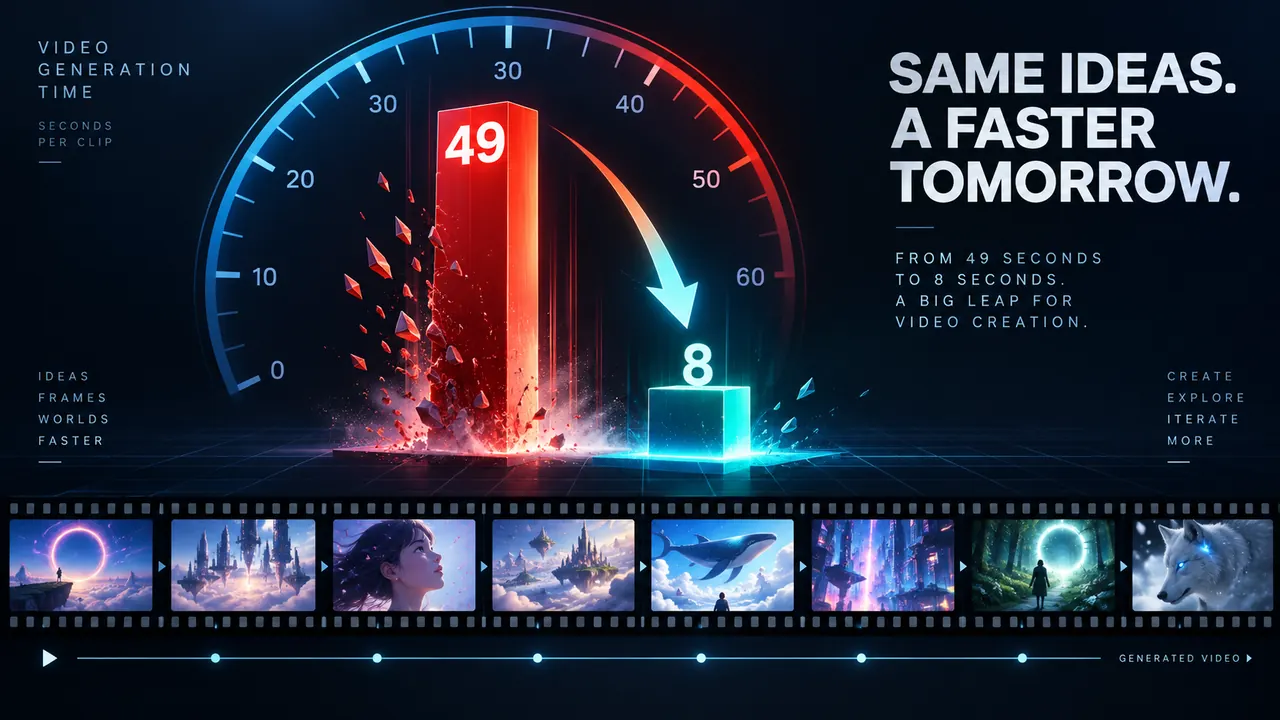
Video Rebirth released HyperFlow, an 8-step LoRA for MiniMax H3 covering T2VA, FL2VA and Ref2VA — rank 256, unmerged bf16 branches, with two-time (t, r) conditioning where r equals 1 minus sigma_next. Contributor drbaph converted it to ComfyUI key layout across four files covering full and pruned H3 bases, so it loads in the built-in H3 LoRA loader with no custom node. Documented settings: 8 steps, LoRA strength 1.0, euler/normal or the upstream manual sigma sequence.
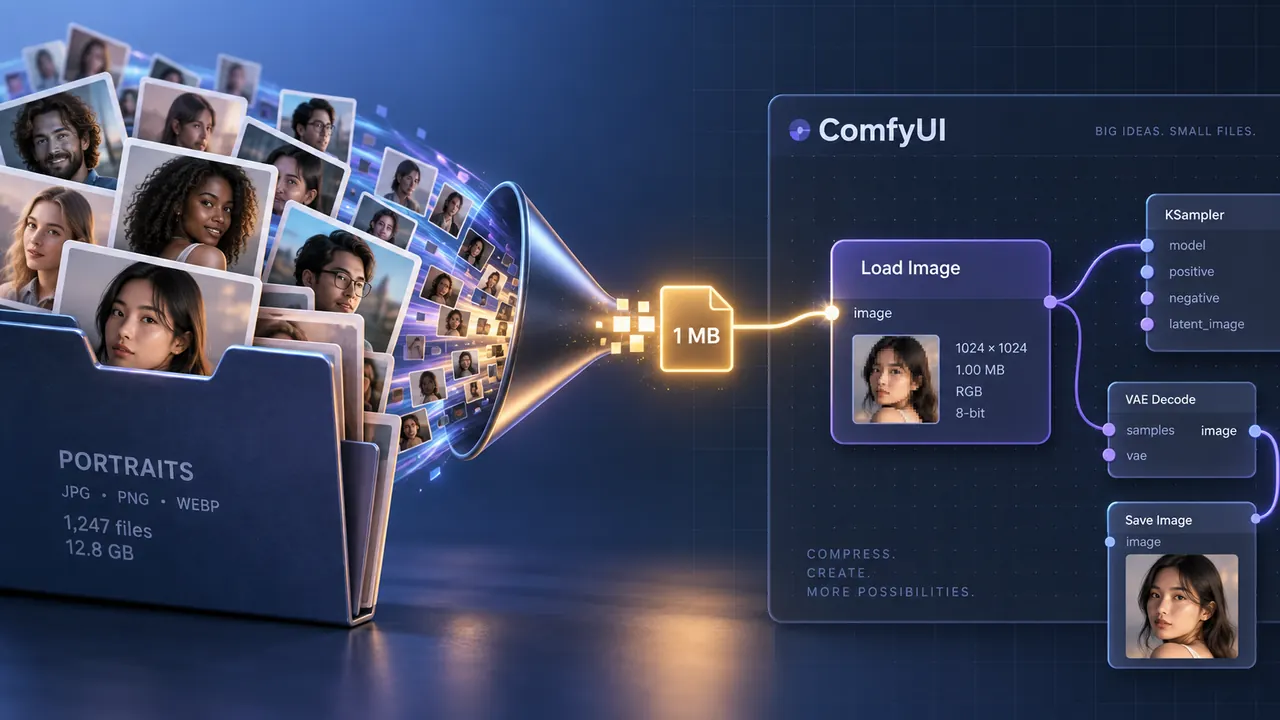
Fizgig v6 packs a folder of reference photos into a single 1 to 1.6 MB .safetensors file, tuned against a frozen H3 rather than trained as a LoRA — minutes instead of a training job, and the basic flavor needs no captions. RefMod Studio lets you A/B a mod against no-mod on the same seed before you ever open ComfyUI. Point the output folder at models/refmods once and it works across both ref2va and fl2va paths.
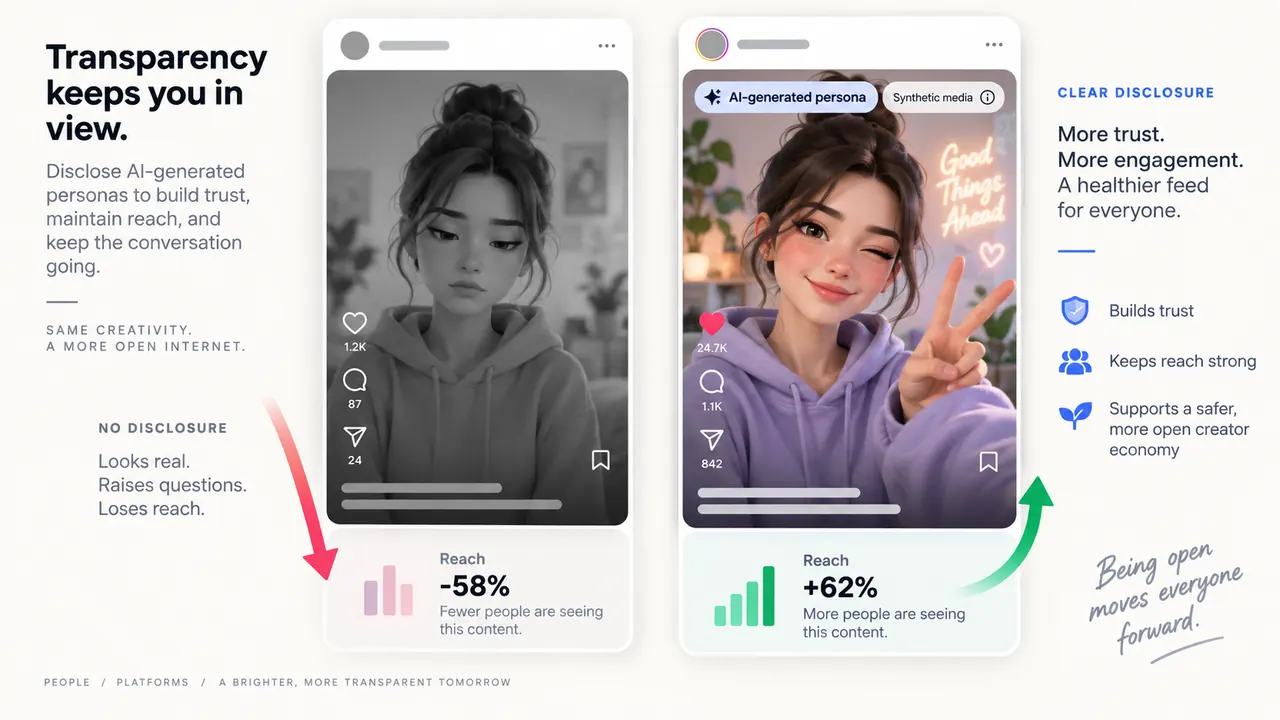
Meta is telling accounts built around an AI persona to add the new "AI-generated profile" label — skip it and the algorithm marks the content non-recommendable, which kills reach and the monetization that depends on it. Properly labeled AI content stays fully eligible for brand deals, affiliate, subscriptions, gifts and bonus programs. The AI info tag now runs across Feed, Reels and Explore.
Tallies circulating this month put the scale at roughly 4.7 billion lifetime views erased, 35 million subscribers affected, and an estimated $10 million in annual creator revenue wiped. Documented casualties include a 588K-sub Bible stories channel at about $30K/month and an exam-prep channel at $7,500/month. The trigger is scale without a human fingerprint — not AI use itself — and AI short films and series still clear $2 to $6 RPM when the channel reads as authored.
XGEN Labs released an egocentric interactive model built on MiniMax H3 that generates first-person video and audio from an action sequence, reference images and observation history — you literally type a camera path with W, A, S, D or a dash to hold. It handles object interaction and character dialogue with video and audio generated together. JING-Flash-v1 is a four-step bidirectional model, meaning the whole action sequence is known up front; the truly causal, key-by-key version isn't out yet.
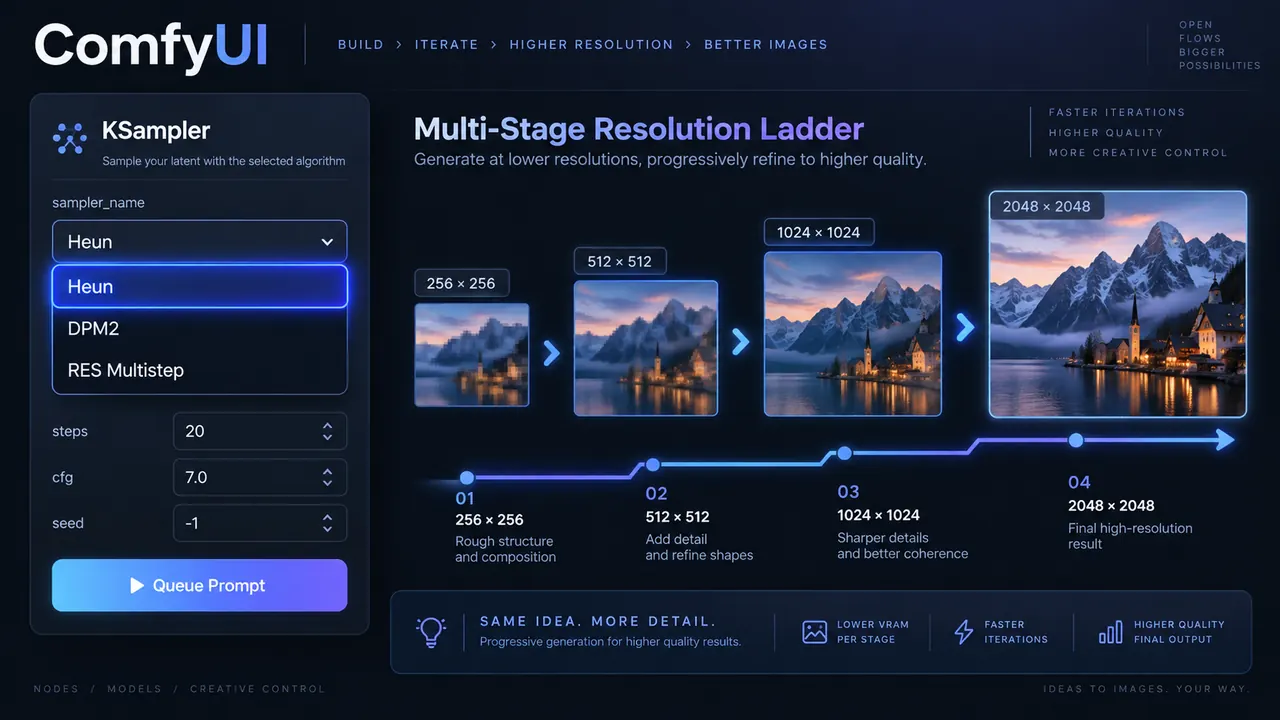
The SPEED sampler's V2 update adds Euler, Heun, DPM2, Exp Heun 2 X0 and RES Multistep, up from Euler-only, and Sigma Harvest is now sampler-aware so calibration reflects what you're actually running. It drops in for SamplerCustomAdvanced using the same noise, guider, sigmas and latent_image wiring. You pick 2, 3 or 4 resolution stages — 0.5 to 1.0, a third-two-thirds-full ladder, or quarter steps.
Alibaba put Wan 3.0 into public beta August 6 with 30-second single-pass clips and document-to-video input, priced at 0.3 to 1.2 yuan per second by resolution. As of mid-September there are still no official Wan 3.0 weights published, and Wan 2.2 remains the last open-weighted video flagship in the family. The Apache 2.0 releases this cycle were WanSong, Wan-Dancer-14B and Wan-Streamer — adjacent tools, not the flagship.
TikTok's 2026 policy requires visible labeling on AI-generated visuals and audio depicting realistic people or scenes, and the platform reads C2PA Content Credentials to flag synthetic media even when you don't self-disclose. AI used purely for text, planning or post that doesn't alter how people or scenes look is exempt. It remains disclosure, not prohibition — but the detection side is no longer opt-in.